If you work with Linux servers, Docker containers, Kubernetes, or cloud-based applications, you may eventually come across an error called exit code 137. At first glance, it looks like a random technical number that gives little information about what went wrong. However, this code actually tells you something very specific about how your application stopped running.
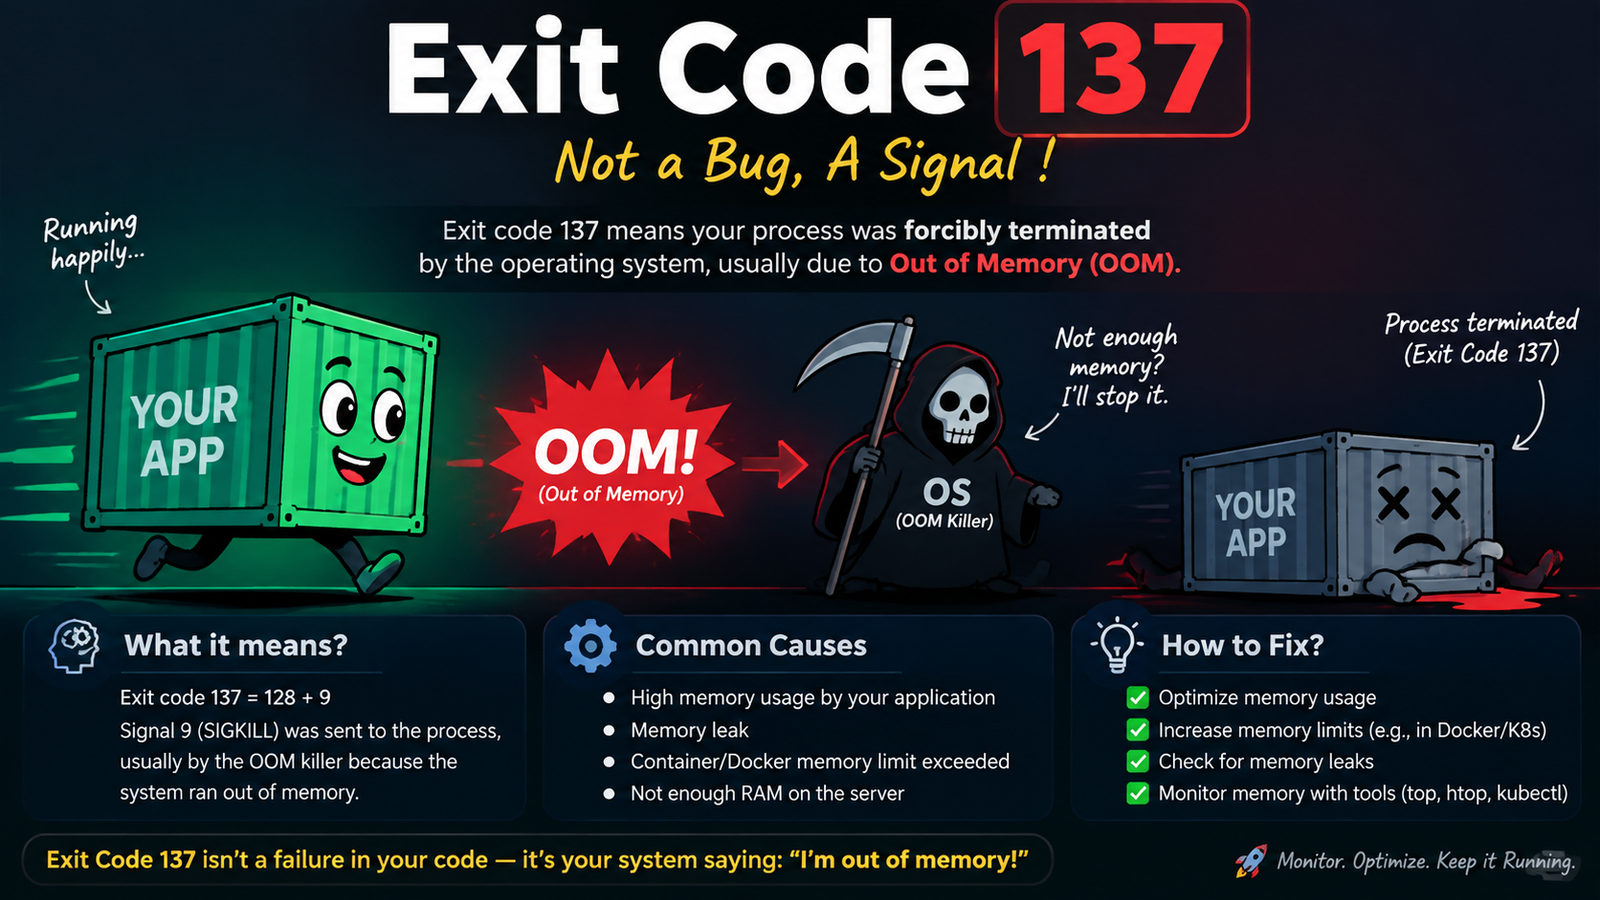
Exit code 137 usually means that a process was terminated by the operating system because it used too much memory. In technical terms, it happens when a process receives a SIGKILL signal (signal 9) after exceeding available memory limits. Since the process is forcefully stopped, it does not get the chance to shut down gracefully or save important data before termination.
This issue has become increasingly common as more applications move into containerized and cloud environments. Developers often run multiple services inside Docker containers or Kubernetes pods, where memory limits are strictly controlled. When an application consumes more memory than it is allowed to use, the system steps in and kills the process to protect overall stability.
Understanding exit code 137 is important because it is not just an error message; it is a warning sign about resource management. Instead of simply restarting the failed application, developers need to investigate why memory usage increased and how to prevent similar failures in the future.
What Is Exit Code 137 and What Does It Actually Mean?
Exit code 137 is a Linux process termination status that indicates a program was killed by a SIGKILL signal. The number 137 comes from adding the signal number 9 to the standard exit code calculation: 128 + 9 = 137. Signal 9 represents SIGKILL, which immediately stops a running process without allowing cleanup operations.
In simple words, when you see exit code 137, the operating system is saying, “This application was using more memory than it should, so I had to force it to stop.” The system does this to prevent one process from consuming all available resources and causing other applications or services to crash.
Unlike normal application errors, exit code 137 is usually not caused by incorrect syntax, broken code logic, or configuration mistakes. Instead, it is related to resource limitations. The application may work perfectly during testing but fail in production because real-world traffic, larger datasets, or longer processing times increase memory consumption.
For example, imagine a data processing application that loads millions of records into memory. During development, it may only process a small sample dataset and run without problems. Once deployed with real production data, memory usage grows significantly, causing the operating system or container platform to terminate it with exit code 137.
Common Causes Behind Exit Code 137
The most common reason behind exit code 137 is memory exhaustion. Every application requires a certain amount of RAM to store temporary data, execute operations, and maintain internal processes. If the application demands more memory than the system or container allows, it becomes a candidate for termination.
One frequent cause is a memory leak inside the application. A memory leak occurs when software continues allocating memory but fails to release unused resources. Over time, memory usage gradually increases until the application consumes all available resources. This problem is especially common in long-running services such as APIs, background workers, and database-related applications.
Another major cause is incorrect memory configuration. In container environments, administrators often define memory limits to control resource usage. For example, a Docker container may be limited to 512 MB of RAM. If the application requires 1 GB during peak operation, the container runtime may terminate it and return exit code 137.
Large file processing is another situation where this error appears frequently. Applications that handle videos, images, logs, backups, or large datasets may suddenly require much more memory than expected. Without proper streaming techniques or memory optimization, these tasks can easily exceed available limits.
Exit Code 137 in Docker Containers
Docker users commonly encounter exit code 137 because containers operate with specific resource boundaries. Unlike traditional applications running directly on a server, containers are often assigned maximum memory limits. These restrictions help prevent one container from affecting the performance of others.
When a Docker container reaches its memory limit, the Docker runtime communicates with the Linux kernel. The kernel then uses the Out-Of-Memory (OOM) mechanism to identify processes consuming excessive memory. If the container cannot reduce its memory usage, the main process inside the container gets killed, resulting in exit code 137.
A typical example is running a web application inside Docker with a memory limit of 1 GB. During normal usage, the application may consume only 600 MB. However, during high traffic periods, background jobs, caching operations, or large database queries may increase memory usage beyond 1 GB. Docker then stops the container, and users see exit code 137.
To diagnose Docker-related exit code 137 issues, developers should check container memory settings, monitor resource consumption, and review application logs. Commands such as Docker statistics monitoring can help identify whether memory usage consistently approaches the container limit.
Exit Code 137 in Kubernetes Environments
Kubernetes environments are also highly associated with exit code 137 errors because Kubernetes manages resources through containers and pods. Each container in a Kubernetes cluster can have defined memory requests and memory limits. These settings determine how much memory an application receives and when it becomes eligible for termination.
When a Kubernetes container exceeds its memory limit, Kubernetes marks the container as terminated due to an Out Of Memory event. The container status often shows information such as “OOMKilled,” and the application exits with code 137. This is Kubernetes protecting the cluster from unstable workloads.
A common mistake in Kubernetes deployments is setting memory limits too low. Developers sometimes choose small values to reduce infrastructure costs, but this can create frequent crashes when applications experience unexpected workloads. Proper resource planning is necessary to balance performance, reliability, and cost.
Another Kubernetes-related cause is poor workload optimization. If a service continuously consumes increasing amounts of memory, simply increasing the memory limit may only delay the problem. Developers should investigate application behavior, memory allocation patterns, and possible leaks before increasing resources.
How to Diagnose Exit Code 137 Effectively
The first step in diagnosing exit code 137 is confirming that memory exhaustion is actually the cause. Check system logs, container logs, and monitoring tools to identify whether an Out-Of-Memory event occurred. In Linux environments, system messages often provide details about which process was terminated.
For Docker containers, reviewing container resource usage is a practical starting point. Monitoring memory consumption over time can reveal whether the application steadily increases memory usage or suddenly spikes during specific operations. This information helps distinguish between memory leaks and temporary workload increases.
Application-level monitoring is also extremely valuable. Tools that track memory usage, garbage collection behavior, and performance metrics can reveal hidden problems inside the code. For example, a Java application may require garbage collection tuning, while a Python application may need investigation into unused objects remaining in memory.
Developers should also examine recent changes before the failure occurred. New features, dependency updates, configuration changes, or increased traffic levels can introduce unexpected memory requirements. Comparing system behavior before and after these changes often helps identify the root cause faster.
Practical Ways to Fix Exit Code 137
The most straightforward solution is increasing the available memory, but this should not always be the first choice. Providing more memory can solve the immediate problem, but it does not address underlying issues such as inefficient code or memory leaks.
Optimizing application memory usage is usually the better long-term approach. Developers can reduce unnecessary data storage, improve database queries, process large files in smaller sections, and release unused resources properly. Small improvements in memory management can significantly reduce the chances of exit code 137.
For containerized applications, adjusting memory limits may be necessary. Docker and Kubernetes allow administrators to increase memory allocations based on application requirements. However, these values should be based on actual monitoring data rather than guesses.
Another useful strategy is implementing better workload handling. Instead of processing everything at once, applications can use queues, batching systems, or streaming methods. This approach keeps memory usage predictable and prevents sudden resource spikes.
Preventing Exit Code 137 in Future Deployments
Preventing exit code 137 requires a proactive approach to resource management. Waiting until production failures happen can lead to downtime, customer impact, and difficult troubleshooting situations. Regular monitoring and testing are essential parts of maintaining reliable applications.
Load testing is one of the best ways to identify memory problems before deployment. By simulating realistic traffic and workloads, developers can observe how applications behave under pressure. This makes it easier to adjust memory settings and optimize performance before users experience problems.
Setting realistic resource limits is also important. Extremely low memory limits can cause unnecessary failures, while extremely high limits may waste infrastructure resources. The goal is to find a balanced configuration based on actual application behavior.
Continuous monitoring tools can provide valuable insights into memory trends. Instead of only checking when an application crashes, teams should track memory usage patterns over days or weeks. Gradual increases in memory consumption often reveal problems before they become serious failures.
Final Thoughts on Exit Code 137
Exit code 137 may look like a complicated system error, but its meaning is relatively straightforward: a process was forcefully terminated because it exceeded available memory resources. Whether you are working with Linux, Docker, Kubernetes, or cloud infrastructure, understanding this error can save significant troubleshooting time.
The key to handling exit code 137 is looking beyond the immediate crash. Restarting a container may bring an application back online temporarily, but the real solution comes from identifying why memory usage became too high in the first place.
By monitoring resource usage, optimizing application performance, setting appropriate memory limits, and testing workloads properly, developers can greatly reduce the chances of encountering this issue. Memory management is an ongoing process, and exit code 137 serves as a useful reminder that every application needs the right balance of resources and efficiency.
Frequently Asked Questions About Exit Code 137
What does exit code 137 mean?
Exit code 137 means that a running process was forcefully terminated by the operating system because it exceeded the available memory limit. The number is related to the SIGKILL signal, which has a value of 9, combined with the standard process exit code calculation of 128 + 9.
This error commonly appears in Linux systems, Docker containers, Kubernetes environments, and cloud platforms. It usually indicates that the application required more memory than the system or container was allowed to use.
Is exit code 137 always caused by a memory issue?
In most cases, yes. Exit code 137 is strongly associated with memory exhaustion and Out-Of-Memory (OOM) termination. When the system detects that a process is consuming too many resources, it may kill that process to protect overall system stability.
However, the exact reason behind excessive memory usage can vary. It may be caused by memory leaks, inefficient code, large data processing tasks, incorrect resource limits, or unexpected traffic spikes.
How do I fix exit code 137 in Docker?
To fix exit code 137 in Docker, start by checking the container’s memory usage and configured limits. If the container does not have enough memory allocated, increasing the memory limit may resolve the immediate issue.
For a long-term solution, investigate why the application is consuming too much memory. Optimizing code, reducing unnecessary data storage, improving queries, and processing large tasks in smaller batches can help prevent future crashes.
Why does Kubernetes show OOMKilled with exit code 137?
Kubernetes shows OOMKilled when a container uses more memory than the limit defined in its configuration. Kubernetes relies on these limits to manage cluster resources and prevent one application from affecting other workloads.
When a container crosses its memory limit, Kubernetes terminates it, and the process usually exits with code 137. Reviewing memory requests, limits, and application performance can help solve the problem.
Can increasing memory limits permanently solve exit code 137?
Increasing memory limits can solve the problem if the application simply requires more resources than currently allocated. For example, a large data-processing job may naturally need additional memory.
However, increasing memory is not always a permanent solution. If the application has a memory leak or inefficient resource usage, it may continue consuming more memory over time and eventually fail again.
How can I check what caused exit code 137?
To identify the cause of exit code 137, check system logs, container logs, and monitoring data. Look for Out-Of-Memory events, memory usage spikes, and information about the process that was terminated.
In container environments, tools that display CPU and memory consumption can help identify whether the application consistently reaches its memory limit or experiences occasional spikes.
Does exit code 137 mean my code is broken?
Not necessarily. Exit code 137 does not always mean there is a coding mistake. It indicates a resource problem, which may come from application design, configuration settings, workload size, or infrastructure limitations.
A well-written application can still encounter exit code 137 if it is deployed with insufficient memory resources or receives more workload than expected.
How can I prevent exit code 137 in production?
Preventing exit code 137 requires proper monitoring, testing, and resource planning. Developers should track memory usage, perform load testing, and configure realistic memory limits based on actual application requirements.
Regular code reviews, performance optimization, and monitoring memory trends can also help identify potential problems before they cause production failures.
What is the difference between exit code 137 and exit code 1?
Exit code 137 usually indicates that a process was killed due to memory-related issues, while exit code 1 is a general application error that can happen for many reasons, such as incorrect configuration, invalid input, or failed operations.
The troubleshooting approach is different for both errors. Exit code 137 requires investigating memory and resource usage, whereas exit code 1 requires examining application logs and error messages.
Should I restart a container after receiving exit code 137?
Restarting a container may temporarily restore service availability, but it does not solve the underlying problem. If the application continues exceeding memory limits, the container may fail again.
The better approach is to investigate memory consumption, identify the root cause, and make appropriate changes to application code, infrastructure settings, or resource allocation.
Also Read: SEO Services by Garage2Global